
Stop babysitting your AI agent's backend code.
Describe the endpoint. We run it.
Just say the word. Coding agents hand you hundreds of files you still have to read, review and maintain. Semantyx skips the files: describe what the endpoint should do in plain English, and the engine runs that description directly as a live API — against your own database.
// generated: src/controllers/ticket.controller.ts
import { Request, Response, NextFunction } from 'express';
import { prisma } from '../lib/prisma';
import { sendNotification } from '../services/notification';
export async function resolveTicket(req: Request, res: Response, next: NextFunction) {
  try {
    const { ticket_id } = req.body;
    if (!ticket_id) return res.status(400).json({ error: 'Missing ticket_id' });
    const ticket = await prisma.ticket.findUnique({ where: { id: ticket_id } });
    if (!ticket) return res.status(404).json({ error: 'Not found' });
    if (ticket.status === 'resolved') {
      return res.status(400).json({ message: 'Ticket already resolved' });
    }
    const updated = await prisma.ticket.update({
      where: { id: ticket_id },
      data: { status: 'resolved', resolved_at: new Date() }
    });
// 180 more lines of boilerplate, try-catch, Prisma config, and route binding...Add a POST endpoint at /api/tickets/resolve. Look up the support ticket by the id in the request. If it has already been resolved, reject it with a 400 and the message "Ticket already resolved". Otherwise mark it resolved, stamp the time, and return the ticket.
Generated code is still code you have to own.
Writing code is only 10% of software engineering. The other 90% is debugging, securing, and maintaining it. By using AI to flood repositories with source files, teams solved the 10% creation bottleneck by exponentially compounding the 90% maintenance debt.
Code is a liability, not an asset.
Every line of source code you commit requires a build pipeline, linting rules, dependency vulnerability patching, runtime container orchestration, and on-call debugging.
Semantyx bypasses the code generation cycle entirely. Your natural language intent is compiled into a verifiable, deterministic Abstract Syntax Tree that runs natively on our high-performance runtime.
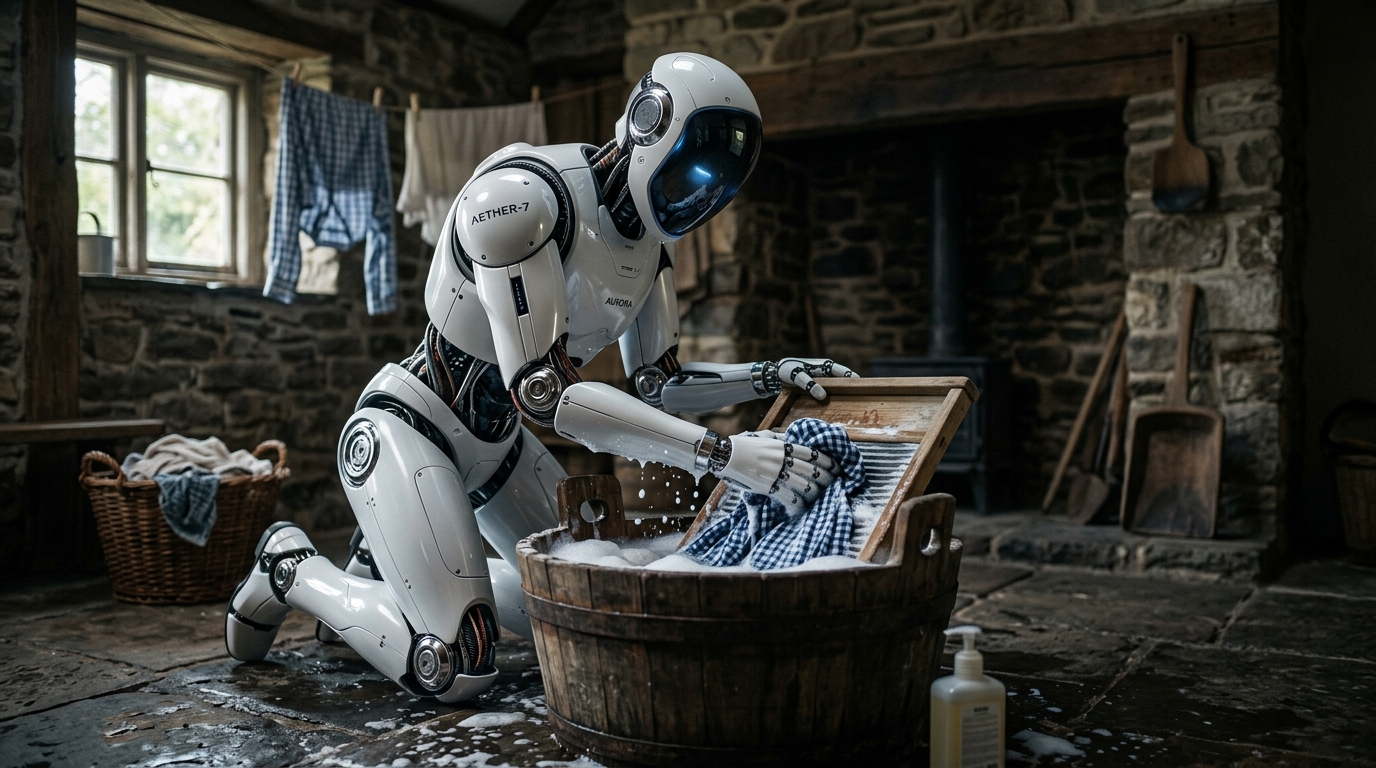
Making an AI write raw code is building a humanoid robot to use a washboard.
Impressive, and still the wrong machine. Semantyx builds the washing machine: you describe the outcome, and the engine runs it — no source files in between.
Engineered for high-durability backends.
Every layer of Semantyx is built for production reliability. No fragile glue code, no package decay, no hidden technical liabilities.
Zero Source Files
You do not own, maintain, or update source code files. Semantyx stores and executes the compiled Abstract Syntax Tree directly.
PostgreSQL Schema Enforcement
Validates table, column, and foreign key references against your live schemas at compile time. Zero runtime mismatch.
Compiled, Not Generated
Your description compiles into .NET 9 expression trees the engine runs directly. No container to cold-start, no build step, no files emitted.
Bring Your Own Database
Point Semantyx at your own PostgreSQL instance. Your data stays where it already lives, under credentials you control.
In-Memory PII & Secret Sanitization
Tag any symbol as [secret] or [pii]. The engine automatically masks them across structured telemetry, logs, and HTTP traces.
Per-Step Execution Traces
Every run records each step with its inputs, outputs and timing, so you can see exactly where a request did something you did not expect.
Against what you are doing today.
Most teams build a backend endpoint one of two ways: write it themselves, or have a coding agent write it and then review what comes back. Here is how Semantyx compares with both.
| What matters | Hand-written | AI coding agents | Semantyx Runtime |
|---|---|---|---|
| Time to a working endpoint | Days — scaffolding, wiring, deploying | Hours, plus the review you still have to do | Minutes, from one description |
| What you maintain afterwards | All of it, and you wrote it | All of it, written by something else | The plain-language steps, nothing underneath |
| Ongoing cost | Developer time | Tokens, plus the developer supervising them | Flat platform cost — pricing announced at launch |
| Where your data lives | Your database | Your database | Your database — bring your own PostgreSQL |
| Debugging a failed request | Logs you remembered to add | Logs the agent decided to add | Per-step trace with inputs, outputs and timing |
| Sensitive fields in logs | Masked only where you remembered to | Frequently printed in full | Tag a field [pii] or [secret]; masking is automatic |
| Leaving | Not applicable | Not applicable | Export to a self-hosted binary (in development) |
No. There is no visual editor to drag boxes around in, your logic is plain text rather than a vendor-only file format, and your data stays in your own PostgreSQL. A self-hosted export is in development.
Stop generating liabilities.
Just say the word.
Describe your endpoint logic in plain English. Watch Semantyx compile it into a deterministic execution tree and serve it as a live, callable API.